From the free course CS323: Numerical Analysis and Computing on Lykke
Midterm 1: Review and Assessment
Key concepts: Solving Linear Systems (Ax=b) · LU Factorization with Pivoting · Iterative Methods (Jacobi, Gauss-Seidel) · Matrix Conditioning · Least Squares Solutions · Computational Cost Analysis
This module consolidates all materials related to the first midterm, which assesses your understanding of numerical linear algebra. It includes a practice exam and solutions covering direct and iterative methods for solving Ax=b, matrix conditioning, computational complexity, and least squares. Use these resources to test your knowledge and prepare for the exam.
Midterm 1: Review and Assessment
This article serves as a comprehensive technical review for the first midterm, focusing on the foundational concepts of numerical linear algebra. The exam will assess your understanding of both the theoretical underpinnings and the practical application of algorithms for solving linear systems. Expect a blend of problems requiring derivations, manual computation on small matrices, and analysis of algorithmic properties like stability and computational cost. Mastering these topics is crucial, as they form the bedrock upon which more advanced numerical methods are built.
1. The Central Problem: Solving Linear Systems (Ax = b)
What It Is
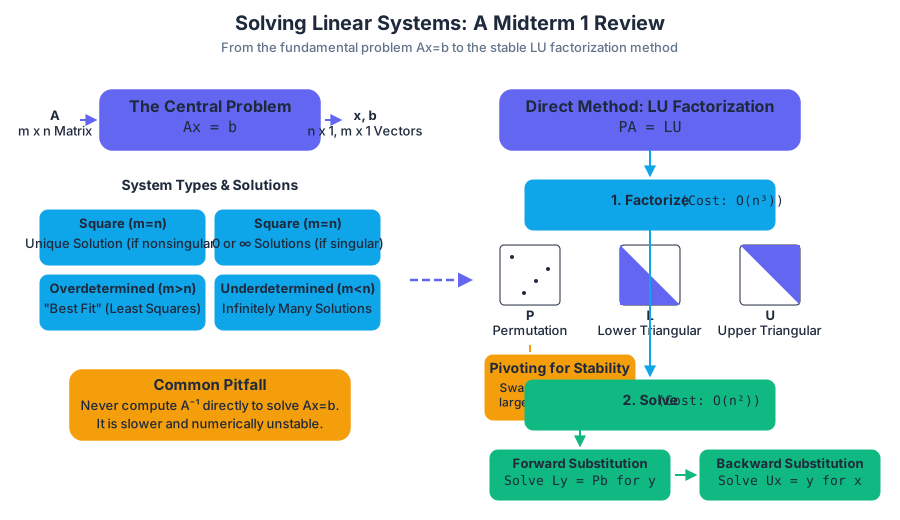
The most fundamental problem in this domain is solving the matrix equation Ax = b.
Ais a knownm x nmatrix of coefficients.xis an unknownn x 1column vector of variables.bis a knownm x 1column vector of constants.
The goal is to find the vector x that satisfies this equation. The nature of the solution depends critically on the dimensions m and n and the properties of the matrix A.
Why It Matters
Linear systems are ubiquitous in virtually every field of science, engineering, and data analysis. They arise from the discretization of differential equations (e.g., in physics simulations and weather forecasting), circuit analysis (Kirchhoff's laws), optimization problems, and statistical modeling (linear regression). The ability to solve Ax = b efficiently and accurately is a cornerstone of modern computational science.
How It Works
The solution's existence and uniqueness are determined by the relationship between m, n, and the rank of A.
| Case | System Type | Condition | Solution |
|---|---|---|---|
m = n |
Square | A is invertible (nonsingular), i.e., det(A) ≠ 0. |
A unique solution exists: x = A⁻¹b. |
m = n |
Square | A is singular, i.e., det(A) = 0. |
Either no solution or infinitely many solutions. |
m > n |
Overdetermined | More equations than unknowns. | Typically no exact solution. We seek a "best fit" (Least Squares). |
m < n |
Underdetermined | Fewer equations than unknowns. | Typically infinitely many solutions. |
This midterm focuses primarily on the square (m=n) and overdetermined (m>n) cases.
Common Pitfalls
- Assuming Invertibility: Never assume a square matrix
Ais invertible without justification. A singular matrix represents a system with redundant or contradictory equations. - Direct Inversion: While the theoretical solution is
x = A⁻¹b, never compute the inverseA⁻¹directly to solve the system. It is computationally more expensive (~3xthe cost of LU factorization) and numerically less stable.
2. Direct Methods: LU Factorization with Pivoting
Direct methods aim to find the exact solution to Ax=b in a finite number of steps, barring any floating-point precision errors. The premier direct method is Gaussian Elimination, which is systematically captured by LU Factorization.
What It Is
LU Factorization is the process of decomposing a square matrix A into the product of a lower triangular matrix L and an upper triangular matrix U.
Definition: For a nonsingular matrix
A, the factorization isA = LU, whereLis a unit lower triangular matrix (ones on the diagonal) andUis an upper triangular matrix.
For numerical stability, we almost always use pivoting, which introduces a permutation matrix P. The factorization then becomes PA = LU.
Why It Matters
Factoring A is the expensive part. Once P, L, and U are known, solving Ax = b becomes remarkably efficient. The original system Ax = b is rearranged to PAx = Pb, and then LUx = Pb. This is solved in two simple steps:
- Forward Substitution: Solve
Ly = Pbfory. - Backward Substitution: Solve
Ux = yforx.
Solving triangular systems is computationally cheap (O(n²)), so after the initial O(n³) factorization, we can solve for different b vectors rapidly.
How It Works
The algorithm is a systematic version of Gaussian elimination. At each step k, we eliminate the entries below the diagonal in column k. The multipliers used for elimination are stored in the lower triangular part, which becomes L.
Pivoting is essential. Without it, the algorithm fails if a zero appears on the diagonal. Even a very small pivot can lead to catastrophic numerical errors due to subtractive cancellation. Partial Pivoting, the most common strategy, involves swapping the current row k with a row i >= k that has the largest absolute value in column k. This ensures that the multipliers are always less than or equal to 1 in magnitude, stabilizing the process. The P matrix keeps track of these row swaps.
Concrete Example
Let's find the PA=LU factorization for A = [[1, 2, 1], [2, 6, 1], [1, 1, 4]].
-
Step 1 (k=1):
- The largest element in the first column is
2(in row 2). Swap row 1 and row 2. P₁ = [[0, 1, 0], [1, 0, 0], [0, 0, 1]].A' = P₁A = [[2, 6, 1], [1, 2, 1], [1, 1, 4]].- Eliminate below the pivot:
R₂' = R₂ - (1/2)R₁. Multiplierl₂₁ = 0.5.R₃' = R₃ - (1/2)R₁. Multiplierl₃₁ = 0.5.
- The matrix becomes:
[[2, 6, 1], [0, -1, 0.5], [0, -2, 3.5]].
- The largest element in the first column is
-
Step 2 (k=2):
- Look at the sub-matrix
[[-1, 0.5], [-2, 3.5]]. The largest element in the first column is-2. Swap row 2 and row 3. P₂ = [[1, 0, 0], [0, 0, 1], [0, 1, 0]]. The matrix is now[[2, 6, 1], [0, -2, 3.5], [0, -1, 0.5]].- Eliminate below the pivot:
R₃' = R₃ - (-1/-2)R₂ = R₃ - 0.5R₂. Multiplierl₃₂ = 0.5.
- The final
Umatrix is:[[2, 6, 1], [0, -2, 3.5], [0, 0, -1.25]].
- Look at the sub-matrix
-
Final Matrices:
U = [[2, 6, 1], [0, -2, 3.5], [0, 0, -1.25]]P = P₂P₁ = [[0, 1, 0], [0, 0, 1], [1, 0, 0]]- The
Lmatrix stores the multipliers, but we must account for the row swaps. The permuted multipliers arel₃₁=0.5,l₂₁=0.5,l₃₂=0.5. L = [[1, 0, 0], [0.5, 1, 0], [0.5, 0.5, 1]]
You can verify that PA = LU.
Code Implementations
A low-level Python/NumPy implementation of LU factorization with partial pivoting.
import numpy as np

def lu_factor_pivot(A):
    """
    Computes the PA=LU factorization of a square matrix A.

    Returns:
        P (numpy.ndarray): Permutation matrix.
        L (numpy.ndarray): Lower triangular matrix.
        U (numpy.ndarray): Upper triangular matrix.
    """
    n = A.shape[0]
    U = A.copy().astype(float)
    L = np.eye(n, dtype=float)
    P = np.eye(n, dtype=float)

    for k in range(n - 1):
        # Find pivot: row with max absolute value in column k
        pivot_row = k + np.argmax(np.abs(U[k:, k]))

        # Swap rows in U, P, and L (for multipliers already computed)
        if pivot_row != k:
            U[[k, pivot_row], :] = U[[pivot_row, k], :]
            P[[k, pivot_row], :] = P[[pivot_row, k], :]
            # Important: Swap the computed parts of L as well
            if k > 0:
                L[[k, pivot_row], :k] = L[[pivot_row, k], :k]

        # Elimination
        for j in range(k + 1, n):
            multiplier = U[j, k] / U[k, k]
            L[j, k] = multiplier
            U[j, k:] -= multiplier * U[k, k:]

    return P, L, U

# Example from above
A = np.array([[1, 2, 1], [2, 6, 1], [1, 1, 4]])
P, L, U = lu_factor_pivot(A)
print("P:\n", P)
print("L:\n", L)
print("U:\n", U)
# Verification
assert np.allclose(P @ A, L @ U)
For a more abstract representation, here is the algorithm in pseudocode.
// Doolittle Algorithm with Partial Pivoting for PA = LU
// Input: n x n matrix A
// Output: P, L, U matrices

Initialize P as identity matrix of size n
Initialize L as identity matrix of size n
Initialize U as a copy of A

for k from 0 to n-2:
    // Find pivot
    p = index of max(|U[i, k]|) for i from k to n-1

    // Swap rows in U, P, and L's computed part
    swap row k and row p in U
    swap row k and row p in P
    swap row k and row p in L for columns 0 to k-1

    // Perform elimination
    for j from k+1 to n-1:
        L[j, k] = U[j, k] / U[k, k]
        U[j, :] = U[j, :] - L[j, k] * U[k, :]

return P, L, U
In practice, you would use a highly optimized library function.
import scipy.linalg

# Real-world usage with SciPy
A = np.array([[1, 2, 1], [2, 6, 1], [1, 1, 4]], dtype=float)

# The 'permute_l=True' argument is crucial for getting a standard L matrix
P_mat, L, U = scipy.linalg.lu(A, permute_l=False)
# Note: SciPy's P is a permutation matrix, not just indices.
# P_mat is the matrix form of the permutation.

# To solve Ax=b
b = np.array([1, 0, 2])
# 1. Factorize
P_lu, L, U = scipy.linalg.lu(A)
# P_lu is a combined PLU matrix, need to solve with lu_solve
x = scipy.linalg.lu_solve((P_lu, L, U), b)
print(f"Solution x: {x}")
Common Pitfalls
- Forgetting
P: When solvingAx=b, a common mistake is to solveLy=binstead of the correctLy=Pb. The permutation must be applied tob. LMatrix Construction: The multipliers are placed atL[i, j]corresponding to the operationRᵢ = Rᵢ - m * Rⱼ. A mix-up here is easy.- Off-by-one errors in loop bounds during manual or coded implementation.
3. Iterative Methods: Jacobi and Gauss-Seidel
Iterative methods take a different approach. Instead of a finite sequence of operations, they start with an initial guess x⁽⁰⁾ and generate a sequence of approximate solutions x⁽¹⁾, x⁽²⁾, ... that ideally converges to the true solution.
What They Are
These are stationary iterative methods based on splitting the matrix A into A = M - N, where M is easily invertible. The system Ax = b becomes Mx = Nx + b, which inspires the iteration:
Mx⁽ᵏ⁺¹⁾ = Nx⁽ᵏ⁾ + b
The choice of M and N defines the method. Let A = D + L' + U', where D is the diagonal of A, L' is the strictly lower triangular part, and U' is the strictly upper triangular part.
- Jacobi Method:
M = D,N = -(L' + U'). - Gauss-Seidel Method:
M = D + L',N = -U'.
Why They Matter
For large, sparse matrices, which are common in scientific computing (e.g., from finite difference or finite element methods), direct methods are prohibitively expensive.
- Memory: LU factorization can cause fill-in, where an initially sparse matrix
Aresults in denseLandUfactors, consuming vast amounts of memory. - Computation: An
O(n³)cost is too high fornin the millions.
Iterative methods only require matrix-vector products, which are very efficient (O(n*k) where k is the average number of non-zero elements per row) for sparse matrices.
How They Work
The update rules can be written component-wise:
-
Jacobi Update:
xᵢ⁽ᵏ⁺¹⁾ = (1/aᵢᵢ) * (bᵢ - Σ_{j≠i} aᵢⱼ * xⱼ⁽ᵏ⁾)All components ofx⁽ᵏ⁺¹⁾are computed using only the components from the previous iterationx⁽ᵏ⁾. This is highly parallelizable. -
Gauss-Seidel Update:
xᵢ⁽ᵏ⁺¹⁾ = (1/aᵢᵢ) * (bᵢ - Σ_{j<i} aᵢⱼ * xⱼ⁽ᵏ⁺¹⁾ - Σ_{j>i} aᵢⱼ * xⱼ⁽ᵏ⁾)The computation forxᵢ⁽ᵏ⁺¹⁾immediately uses the newly computed valuesx₁⁽ᵏ⁺¹⁾, ..., xᵢ₋₁⁽ᵏ⁺¹⁾from the current iteration. This is inherently sequential but often converges faster than Jacobi.
Convergence:*
Theorem: A stationary iterative method
x⁽ᵏ⁺¹⁾ = Tx⁽ᵏ⁾ + cconverges for any initial guessx⁽⁰⁾if and only if the spectral radiusρ(T)of the iteration matrixTis less than 1 (ρ(T) < 1).
The spectral radius is the maximum absolute eigenvalue of T. Computing this is often harder than solving the original system. A simpler, sufficient (but not necessary) condition is:
Sufficient Condition: If
Ais strictly diagonally dominant, both Jacobi and Gauss-Seidel methods are guaranteed to converge. A matrix is strictly diagonally dominant if for every rowi,|aᵢᵢ| > Σ_{j≠i} |aᵢⱼ|.
Comparison of Methods
| Feature | Direct Methods (LU) | Iterative Methods (Jacobi/GS) |
|---|---|---|
| Solution Type | Exact (in theory) | Approximate |
| Computational Cost | O(n³) for dense, O(n²) to O(n³) for sparse |
O(k * nnz) per iteration (nnz=non-zeros) |
| Memory Usage | High, potential for fill-in | Low, only stores A, x, b |
| Applicability | General purpose, robust | Best for large, sparse, diagonally dominant systems |
| Numerical Issues | Stability depends on pivoting | Convergence is not guaranteed |
| Method | Jacobi | Gauss-Seidel |
|---|---|---|
| Update Rule | Uses only values from x⁽ᵏ⁾ |
Uses most recent values available in x⁽ᵏ⁺¹⁾ |
| Convergence Rate | Generally slower | Generally faster (often by a factor of ~2) |
| Implementation | Highly parallelizable | Inherently sequential |
Concrete Example
Solve Ax=b with A = [[4, 1], [2, 3]], b = [1, 2], and x⁽⁰⁾ = [0, 0].
The exact solution is x = [0.1, 0.6].
Jacobi:
x₁⁽ᵏ⁺¹⁾ = (1/4) * (1 - x₂⁽ᵏ⁾)x₂⁽ᵏ⁺¹⁾ = (1/3) * (2 - 2x₁⁽ᵏ⁾)k=0:x₁⁽¹⁾ = 1/4 = 0.25,x₂⁽¹⁾ = 2/3 ≈ 0.667k=1:x₁⁽²⁾ = (1/4) * (1 - 0.667) ≈ 0.083,x₂⁽²⁾ = (1/3) * (2 - 2*0.25) = 0.5
Gauss-Seidel:
x₁⁽ᵏ⁺¹⁾ = (1/4) * (1 - x₂⁽ᵏ⁾)x₂⁽ᵏ⁺¹⁾ = (1/3) * (2 - 2x₁⁽ᵏ⁺¹⁾)k=0:x₁⁽¹⁾ = (1/4) * (1 - 0) = 0.25x₂⁽¹⁾ = (1/3) * (2 - 2*0.25) = 1.5/3 = 0.5k=1:x₁⁽²⁾ = (1/4) * (1 - 0.5) = 0.125x₂⁽²⁾ = (1/3) * (2 - 2*0.125) = 1.75/3 ≈ 0.583
Notice how Gauss-Seidel is already closer to the true solution after just one full iteration.
Code and Mathematical Derivations
A C implementation of Gauss-Seidel for a dense matrix, emphasizing the in-place update.
#include <stdio.h>
#include <math.h>

#define N 3 // Matrix size
#define MAX_ITER 100
#define TOLERANCE 1e-6

void gauss_seidel(double A[N][N], double b[N], double x[N]) {
    double x_old[N];
    int iter = 0;

    while (iter < MAX_ITER) {
        for (int i = 0; i < N; i++) {
            x_old[i] = x[i];
        }

        for (int i = 0; i < N; i++) {
            double sigma = 0.0;
            // Note: j < i uses new x values, j > i uses old x values
            // But since we update x in-place, this is handled automatically.
            for (int j = 0; j < N; j++) {
                if (i != j) {
                    sigma += A[i][j] * x[j];
                }
            }
            x[i] = (b[i] - sigma) / A[i][i];
        }

        // Check for convergence
        double norm_diff = 0.0;
        for (int i = 0; i < N; i++) {
            norm_diff += (x[i] - x_old[i]) * (x[i] - x_old[i]);
        }
        if (sqrt(norm_diff) < TOLERANCE) {
            printf("Converged after %d iterations.\n", iter + 1);
            return;
        }
        iter++;
    }
    printf("Did not converge within %d iterations.\n", MAX_ITER);
}

int main() {
    double A[N][N] = {{4, -1, -1}, {-2, 6, 1}, {-1, 1, 7}};
    double b[N] = {3, 9, -6};
    double x[N] = {0, 0, 0}; // Initial guess

    gauss_seidel(A, b, x);

    printf("Solution: x = [%.4f, %.4f, %.4f]\n", x[0], x[1], x[2]);
    return 0;
}
The mathematical derivation of the iteration matrix T for Gauss-Seidel.
A = D + L' + U'
(D + L' + U')x = b
(D + L')x = -U'x + b

// Iteration form: M x^(k+1) = N x^(k) + b
(D + L')x^(k+1) = -U'x^(k) + b

// Isolate x^(k+1)
x^(k+1) = -(D + L')⁻¹ U' x^(k) + (D + L')⁻¹ b

// By comparison with x^(k+1) = T_GS x^(k) + c
// The Gauss-Seidel iteration matrix is:
T_GS = -(D + L')⁻¹ U'
4. Matrix Conditioning and Numerical Stability
What It Is
The condition number of a square, nonsingular matrix A, denoted cond(A), measures the sensitivity of the solution x of Ax=b to perturbations in the input data A and b.
Definition: The condition number is defined with respect to a matrix norm as:
cond(A) = ||A|| * ||A⁻¹||
A problem with a low condition number (~1) is well-conditioned. A problem with a very large condition number is ill-conditioned.
Why It Matters
In the real world, input data is never perfect. It comes from measurements with finite precision or is stored in finite-precision floating-point numbers. The condition number tells us how much these small input errors can be amplified in the output solution.
Key Insight: The condition number is a property of the problem (the matrix
A), not the algorithm used to solve it. An unstable algorithm can produce poor results for a well-conditioned problem, but even a perfectly stable algorithm will produce an unreliable solution for a sufficiently ill-conditioned problem.
The relative error in the solution is bounded by:
||δx|| / ||x|| ≤ cond(A) * (||δA|| / ||A|| + ||δb|| / ||b||)
This means cond(A) is an amplification factor for the relative errors in A and b. If cond(A) = 10⁶, you can lose up to 6 digits of precision in your solution.
Concrete Example
Consider the Hilbert matrix H₂ = [[1, 1/2], [1/2, 1/3]].
cond(H₂) ≈ 27. It is modestly ill-conditioned.
Let x = [1, 1]ᵀ. Then b = H₂x = [3/2, 5/6]ᵀ.
Now, let's perturb b slightly to b' = [1.51, 0.83]ᵀ.
The new solution x' to H₂x' = b' is x' = [-0.28, 3.54]ᵀ.
A tiny relative change in b (~1%) caused a massive relative change in x (>200%). This is the signature of an ill-conditioned system.
Estimating the Condition Number
Calculating A⁻¹ to find cond(A) is expensive. Practical algorithms estimate it. A common technique (as seen in the programming assignment) is to estimate ||A⁻¹||₁. This relies on the fact that ||A⁻¹||₁ = max_{||z||₁=1} ||A⁻¹z||₁. The goal is to find a vector z that maximizes ||y||₁ where Ay = z. Heuristic methods can often find a z that gives a good estimate of this maximum without testing all possibilities.
Code and CLI Examples
Using NumPy to directly compute the condition number.
import numpy as np

# A well-conditioned matrix (diagonally dominant)
A_well = np.array([[10, 1, 0], [1, 10, 1], [0, 1, 10]])
cond_well = np.linalg.cond(A_well) # Uses L2-norm by default

# An ill-conditioned matrix (Hilbert matrix)
A_ill = np.array([[1, 1/2, 1/3], [1/2, 1/3, 1/4], [1/3, 1/4, 1/5]])
cond_ill = np.linalg.cond(A_ill)
cond_ill_1 = np.linalg.cond(A_ill, p=1) # L1-norm condition number

print(f"Condition number (well-conditioned): {cond_well:.2f}")
print(f"Condition number (ill-conditioned, L2): {cond_ill:.2f}")
print(f"Condition number (ill-conditioned, L1): {cond_ill_1:.2f}")
You can also use command-line tools like Octave for quick checks.
# Using Octave from the command line to check the L1 condition number of a 5x5 Hilbert matrix
octave --eval "A = hilb(5); cond(A, 1)"
# Expected output will be a large number, e.g., ans = 2.0665e+05
Common Pitfalls
det(A)vs.cond(A): A small determinantdet(A)does not necessarily mean the matrix is ill-conditioned. The determinant is sensitive to scaling (e.g.,det(cI) = cⁿ), while the condition number is not.cond(cI) = 1for anyc ≠ 0.- Blaming the Algorithm: Seeing a large error and immediately blaming the algorithm (e.g., "my LU solver is unstable") is a common mistake. The first step should always be to check the condition number of the matrix itself.
5. Overdetermined Systems: Least Squares Solutions
When we have more equations than unknowns (m > n), the system Ax=b is overdetermined and generally has no exact solution. The vector b does not lie in the column space of A. The goal is to find the vector x that makes Ax "closest" to b.
What It Is
The least squares solution is the vector x that minimizes the L2-norm of the residual vector r = b - Ax.
minₓ ||Ax - b||₂²
Why It Matters
This is the foundation of data fitting and statistical regression. If you have a set of data points (tᵢ, yᵢ) and you want to fit a model, like a line y = c₀ + c₁t, you end up with an overdetermined system where the unknowns are the model coefficients c₀ and c₁.
How It Works
The geometric interpretation is that we are looking for the projection of b onto the column space of A. The residual vector r = b - Ax must be orthogonal to every column of A. This orthogonality condition is expressed as:
Aᵀ(b - Ax) = 0
Rearranging this gives the Normal Equations:
Normal Equations:
(AᵀA)x = Aᵀb
This is now a square n x n system for the unknown x. The matrix AᵀA is square and symmetric. If A has linearly independent columns (which is usually the case in fitting problems), then AᵀA is also invertible, and the system has a unique solution.
Concrete Example: Linear Fit
Find the best-fit line y = c₀ + c₁t for the data points (0, 1), (1, 2), (2, 4).
-
Set up the system
Ac = y:c₀ + c₁*0 = 1c₀ + c₁*1 = 2c₀ + c₁*2 = 4This gives:A = [[1, 0], [1, 1], [1, 2]],c = [c₀, c₁]ᵀ,y = [1, 2, 4]ᵀ.
-
Form the Normal Equations
(AᵀA)c = Aᵀy:AᵀA = [[1, 1, 1], [0, 1, 2]] @ [[1, 0], [1, 1], [1, 2]] = [[3, 3], [3, 5]]Aᵀy = [[1, 1, 1], [0, 1, 2]] @ [1, 2, 4]ᵀ = [7, 10]ᵀ
-
Solve the
2x2system:[[3, 3], [3, 5]] [c₀, c₁]ᵀ = [7, 10]ᵀ- Solving this (e.g., via elimination) gives
c₁ = 1.5andc₀ = 5/6 ≈ 0.833. - The best-fit line is
y = 0.833 + 1.5t.
Code Implementations
Solving least squares in Python using both the normal equations and a more stable, direct library function.
import numpy as np

# Data from the example
t = np.array([0, 1, 2])
y = np.array([1, 2, 4])

# Form the matrix A (Vandermonde matrix for a line)
A = np.vstack([np.ones_like(t), t]).T

# Method 1: Normal Equations
AtA = A.T @ A
Aty = A.T @ y
c_normal = np.linalg.solve(AtA, Aty)

# Method 2: Using a dedicated least-squares solver (more stable)
# This typically uses QR factorization internally
c_lstsq, residuals, rank, s = np.linalg.lstsq(A, y, rcond=None)

print(f"Coefficients (Normal Eq.): {c_normal}")
print(f"Coefficients (np.linalg.lstsq): {c_lstsq}")
A high-level library like scikit-learn abstracts this away entirely for machine learning contexts.
from sklearn.linear_model import LinearRegression

# Data must be shaped for sklearn
t_reshaped = t.reshape(-1, 1) # Feature matrix

model = LinearRegression()
model.fit(t_reshaped, y)

# Coefficients are stored in model attributes
c0 = model.intercept_      # c₀
c1 = model.coef_[0]        # c₁

print(f"Intercept (c0): {c0}")
print(f"Coefficient (c1): {c1}")
Common Pitfalls
- Stability of Normal Equations: Forming
AᵀAcan be numerically problematic. It can square the condition number:cond(AᵀA) = (cond(A))². For an already ill-conditionedA, this can lead to a highly inaccurate solution. Methods based on QR factorization are preferred in practice for this reason. - Incorrect Matrix Setup: The most common error is incorrectly constructing the
Amatrix from the basis functions of the model (e.g., for polynomialc₀ + c₁t + c₂t², the columns ofAshould bet⁰,t¹,t²).
6. Computational Cost Analysis
Analyzing the computational cost, or complexity, of an algorithm allows us to predict its performance and scalability. We use Big-O notation to describe the dominant term of the operation count as the problem size n grows.
Why It Matters
A O(n²) algorithm will always outperform a O(n³) algorithm for sufficiently large n. This analysis is critical for choosing the right tool for the job, especially in large-scale applications.
Algorithm Complexities
The fundamental operation is a flop (floating-point operation), typically a combined multiplication and addition.
| Algorithm | Computational Cost (Flops) | Notes |
|---|---|---|
| Vector Dot Product | O(n) |
2n - 1 flops |
| Matrix-Vector Product | O(n²) |
2n² - n flops for a dense n x n matrix |
| Matrix-Matrix Product | O(n³) |
2n³ - n² flops for two dense n x n matrices |
| Forward/Backward Substitution | O(n²) |
~n² flops |
| LU Factorization (Gaussian Elim.) | O(n³) |
~(2/3)n³ flops |
Solving Ax=b via LU |
O(n³) |
Dominated by the factorization step |
| Jacobi / Gauss-Seidel | O(k * n²) |
For a dense matrix, k iterations |
| Jacobi / Gauss-Seidel (Sparse) | O(k * nnz(A)) |
nnz(A) is the number of non-zero elements |
Forming AᵀA |
O(m * n²) |
For A being m x n |
| Solving Normal Equations | O(m*n² + n³) |
Dominated by forming AᵀA and solving |
Key Insight: For direct methods, the cost is dominated by the
(2/3)n³factorization. Once factored, subsequent solves with the sameAare cheap (O(n²)). For iterative methods, the cost depends on how many iterationskare needed for convergence. Ifk << n, iterative methods can be much faster for large, sparse systems.
Source Materials
Study CS323: Numerical Analysis and Computing on Lykke
This course page is free to open: signed out, you can read its first two sections, and signing in, on any plan, opens the rest. The free Lykke Chrome extension syncs your own Canvas courses, so ChatGPT, Claude and Muse can answer from your classes and deadlines. It only reads Canvas.
Add the free extensionSign in to open every sectionAll sections of CS323: Numerical Analysis and Computing · Browse more course pages